OCR Engine Benchmark for Indian Loan Documents
At a glance
| In short | A research study to choose the OCR engine for reading education-loan paperwork, measuring accuracy, Indian scripts, tables, speed and cost on real documents. |
|---|---|
| Question | Build on a managed service like AWS Textract, or on open-source OCR? |
| What I measured | 4 engines on 108 checked values across 11 documents, 4 Indian scripts, and table values on 12 + 30 unseen pages. |
| Answer for text | Tesseract on AWS Lambda: 103/108 values vs Textract's 104/108, at ₹4.90 instead of ₹142.50 per 1,000 pages. |
| Answer for tables | Tesseract + Qwen3-VL: 178/183 values on unseen pages vs Textract Tables' 163/183, at a third of the cost or less. |
| Trade-off | Table pages take about 17 s instead of 6.5 s, so it suits batch work. |
| Tech | Python, Tesseract 5.4, AWS Textract, RapidOCR, PaddleOCR, Qwen3-VL on Amazon Bedrock, AWS Lambda |
| Code | OCR_Research (private repository) |
Flow
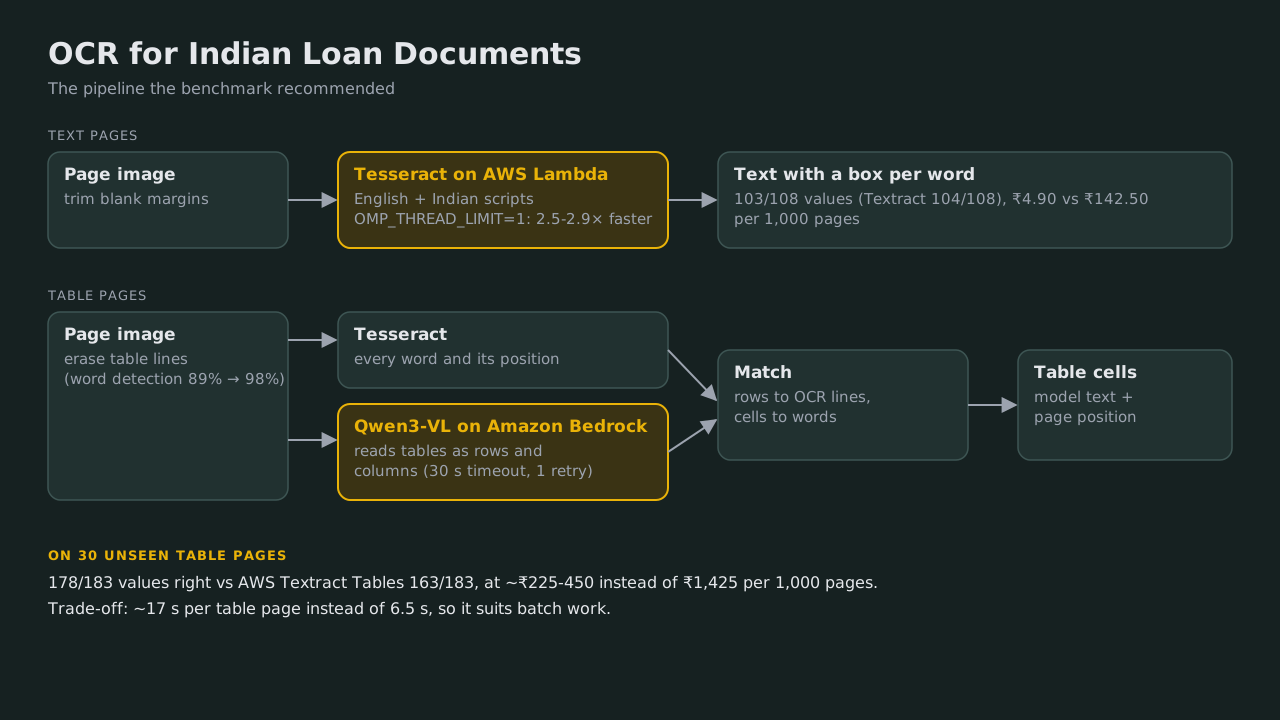
- Page imageloan document
- Clean uptrim margins, erase table lines
- Tesseract on Lambdaevery word + its box
- Qwen3-VLreads tables as rows and columns
- Matchcells to words
- Outputtext and table cells with positions
Key points
- Tesseract was the only engine that read Telugu, Tamil, Devanagari and Kannada; the others returned nothing, without an error
- Deployed and timed on AWS Lambda (Mumbai), not estimated
- Self-hosting came out about 10× cheaper at every volume
- Erasing table lines before OCR raised word detection inside tables from 89% to 98%
Results
| Engine | Values found | Sec / page | Indian scripts |
|---|---|---|---|
| AWS Textract | 104/108 | 3.3 | None |
| Tesseract 5.4 | 103/108 | 1.9 | All four |
| RapidOCR | 101/108 | 5.1 | None |
| PaddleOCR PP-OCRv5 | 99/108 | 17.7 | None |
| Method | Values right | ₹ per 1,000 pages |
|---|---|---|
| Tesseract + Qwen3-VL | 178/183 | ~225-450 |
| Qwen3-VL alone | 178/183 | ~445 |
| AWS Textract Tables | 163/183 | 1,425 |
Architecture
Technical details
- Setting OMP_THREAD_LIMIT=1 made Tesseract 2.5-2.9× faster on Lambda; without it Lambda was slower than a 2019 laptop
- Tesseract with six language packs fits in a 14 MB Lambda zip
- How the table hybrid works: erase lines, Tesseract finds every word and its box, Qwen3-VL reads rows and columns, then each cell is matched to its words
- The unseen-page answer key was written before either system ran, and those pages were not used for tuning
- Things that did not work: asking the model for word ids, and splitting pages into strips (slower and less accurate)
- OCR
- document AI
- Tesseract
- AWS Textract
- Qwen3-VL
- Amazon Bedrock
- AWS Lambda
- Indic OCR
- table extraction
- cost optimization
The code for this project is private, so there is no public link.
All projects