On-Demand Multimodal RAG: A Cost-Efficient Approach to Document Analysis with Selective Page Rendering
At a glance
| Problem | Technical PDFs keep key facts in diagrams, tables and equations. Text-only RAG loses them, OCR is slow, and sending the whole PDF to an LLM is very expensive. |
|---|---|
| Idea | Search the text as usual, then turn only the few matching pages into images and send those to a multimodal LLM. |
| Result | 94.2% accuracy, 97.3% cheaper than sending the full document, 89.5% faster than OCR pipelines. |
| Tested on | A 165-page metallurgy manual (47 diagrams, 23 tables) with 50 questions of 5 types |
| Tech | PyMuPDF, LangChain splitter, Google embedding-001, FAISS, Gemini 2.0 Flash, FastAPI, Streamlit, Docker |
| Published in | 2026 IEEE International Conference on Intelligent Electronics & Computational Systems (IECS) |
| Where & when | July 2026 · Bhopal, India |
| Publisher | IEEE (2026) |
How it works
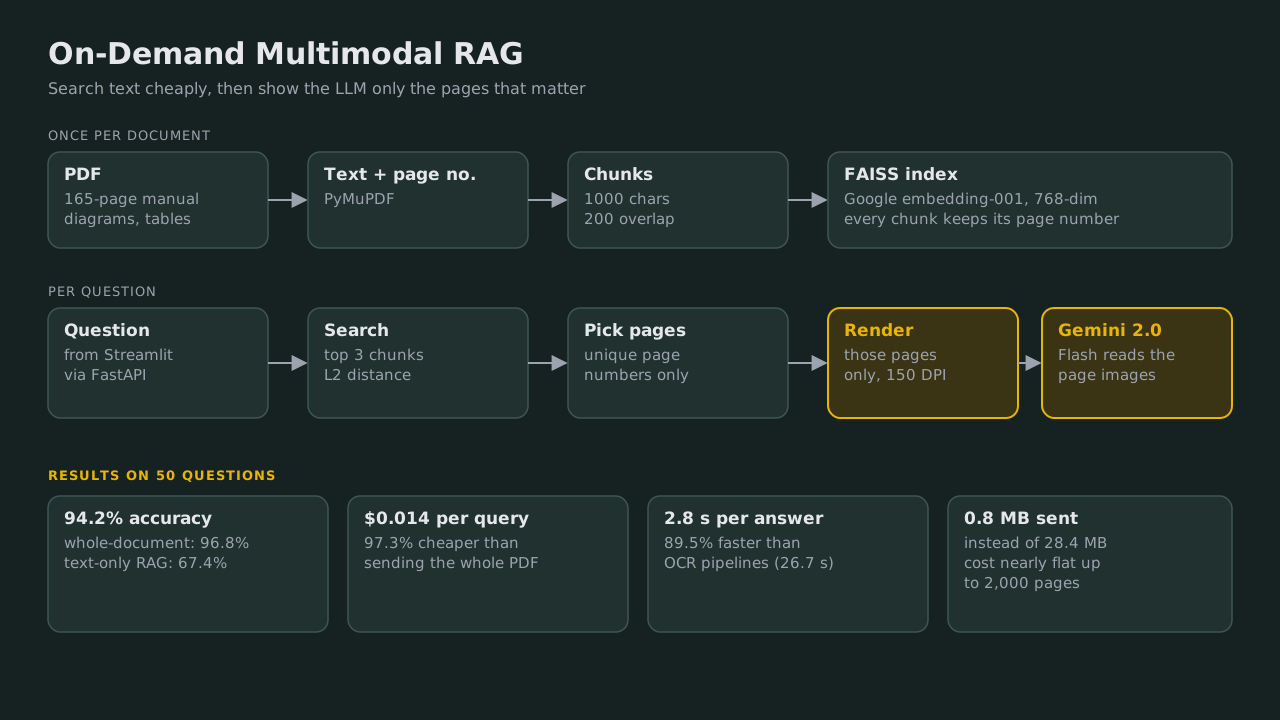
- PDFtext extracted with PyMuPDF
- Chunk + embed1000 chars, 200 overlap, page tagged
- SearchFAISS top-3 chunks
- Pick pagesunique page numbers
- Renderonly those pages, 150 DPI
- AnswerGemini 2.0 Flash reads the images
Key points
- Indexing stays cheap: only the text is embedded, but every chunk remembers its page number
- At question time the top 3 chunks point to a few pages; only those pages are rendered (150 DPI PNG)
- The multimodal LLM sees the real page, so it can read the diagram, table or equation itself
- Near full-document accuracy (94.2% vs 96.8%) at about 1/37th of the cost
- Cost stays almost flat as documents grow: $0.012 to $0.018 per query from 50 to 2,000 pages
Results
| Approach | Accuracy | Latency | Cost per query |
|---|---|---|---|
| On-Demand Multimodal RAG | 94.2% | 2.8 s | $0.014 |
| Text-only RAG | 67.4% | 1.9 s | $0.003 |
| OCR-based RAG | 78.6% | 26.7 s | $0.048 |
| Whole document to the LLM | 96.8% | 52.3 s | $0.516 |
| Hybrid | 88.2% | 31.4 s | $0.124 |
| Question type | Accuracy |
|---|---|
| Text | 98% |
| Diagram | 93% |
| Table | 92% |
| Equation | 91% |
| Mixed (text + visuals) | 95% |
| Pages | This approach | Whole document |
|---|---|---|
| 50 | $0.012 | $0.156 |
| 2,000 | $0.018 | $6.250 |
Architecture
More numbers and details
- Latency split: 0.4 s retrieval, 0.6 s page rendering, 1.8 s LLM
- Data sent per question: 0.8 MB instead of 28.4 MB for the whole document (97.2% less)
- 10,000 questions on a 500-page document: about $160 instead of $15,630
- 50 parallel questions finish in 8.4 s, against 142.7 s for the whole-document approach
- Served through FastAPI (/chat, /health) with a Streamlit UI, packaged in Docker
- Retrieval uses L2 distance in FAISS; embeddings are 768-dimensional
- Generative AI
- Multimodal RAG
- Document AI
- LLM Cost Optimization
- Gemini
- FAISS